commentary, products, supply chain, syndicate

Software Composition Analysis is Finally Dead – Good Riddance

There is a long history of products that were solutions looking for problems, but none were as exasperating, futile, and devoid of application like software composition analysis, or SCA, the dumb database of security “products”. More ambulance-chasing than providing anything useful, SCA vendors were the personal injury lawyers of the technology world. Initially, they started life as an attempt to help enterprises get a handle on the vast quantities of open source dependencies and frameworks they used to build applications, especially with respect to license compliance. That proved to be a pretty limited source of revenue, however, so SCA vendors moved on to something they could seek legitimate rent from: scaring the bejesus out of CIOs everywhere and convincing them that open source was scary stuff that needed to be held at arm’s length no matter the cost. That is to say, they morphed into a security product category and spent their time convincing customers that they were at great risk from all this open source stuff, and only the SCA vendors could help customers avoid an apocalyptic end. It didn’t help that some rather large enterprises misconfigured their systems and allowed hackers to exfiltrate sensitive data – I’m looking at you Equifax.

These data breaches would have been prevented by better security processes and more secure configurations, but it was the SCA vendors that decided to emphasize the role of open source software. It was the SCA vendors that exaggerated the exploitability of every published security vulnerability, no matter how little it applied to a given application’s context, because SCA vendors didn’t care about context. Even the log4j vulnerability, as bad as it was, was only vulnerable in specific circumstances. But good luck explaining that one to your CISO after the SCA vendors had their way. It was the SCA vendors that prevented enterprises from participating in open source communities because they convinced their customers that collaborating upstream would dirty their bottoms and give them a case of the ick. it’s because of the SCA vendors that I have had great difficulty convincing technology leaders of the value of contributing to open source projects. So no, I will shed no tears for the death of an industry category that caused more harm than good and is at least partially responsible for the terrible state of affairs that is open source maintainership.

What is SCA?

For those who never had the misfortune of being subjected to these “products”, you may be forgiven for wondering just what all the fuss is about and why you should care. here is a very simple overview:

  • Take a source code repository, probably in git, and look at the language it’s written in. If it’s python-based, there will be a file called “requirements.txt” and if it’s Java-based, there will be a file called “pom.xml”.
  • Those files contain lists of libraries or software “dependencies” that are needed to use or run the software in your source code repository
  • The SCA scanner looks at those libraries, determines if there are other dependencies that will be used but are not on the list (I’m not going to get into the details of this), and analyses their metadata. Note: the SCA scanner does not actually scan the software; it only scans the metadata that describes the software: version numbers, licensing, file size, etc
  • After compiling a list of all the dependencies it can find, the SCA scanner phones home and compares your metadata to its database, looking for version matches
  • In its massive metadata library, the SCA scanner looks up published security vulnerabilities and determines the likelihood that your software is using vulnerable libraries, based on the matches it finds
  • The SCA vendors often supplement the publicly available vulnerability data with their own proprietary research data that they don’t share because why would they want to solve security problems? That doesn’t increase their revenue share
  • The SCA scanner then provides you a list of vulnerable software and gives you a score of how risky it is based on published security analysis.

This is SCA scanning in a nutshell. Note that at no point do they actually analyze any software. They only match metadata with security data and then give you their best guess as to whether it applies to you. Given that they are incentivized to amplify whatever risk you actually face, don’t count on them being very accurate or proactively removing false positives. They would much rather terrify you into believing you have a severe problem that you need to pay millions of dollars to rectify. SCA vendors have no idea if a particular vulnerability makes your software less secure (this is changing, but these vendors have been loathe to provide this context, because it undermines their value proposition). At its heart, an SCA scanner is a predictive analysis tool that tries to tell you how much security risk you have incurred with your software. If I modify a library or its configuration to improve the security, the SCA tool isn’t smart enough to understand that and will simply label your modified software with the same metadata analysis as the unmodified version. It’s a dumb tool that abhors nuance and besides, it’s better for the SCA vendor if they can tag as many libraries as possible with the high severity security vulnerability label.

It Was Never All That

You could argue that SCA scanning had an important role in improving your security posture, and indeed a few well-known data breaches underscore that fact. But what is also true is that in every one of those breaches, security perimeters, network proxy configuration, and service reachability were even more important, because you can’t exploit a vulnerability if you can’t get to it. Multiple layers of defense are, of course, important, and finding and fixing a flaw that allows for remote code execution should clearly be a priority, but the vast majority of enterprise software is at least 2 layers of defense away from any attacker, which is why, if I’m an attacker, I’m going to spend my time exploiting the most vulnerable line of defense: the humans with elevated privileges. And indeed, aside from the Equifax attack in 2017, we just haven’t seen many incidents that exploited open source vulnerabilities. The vast majority have been social engineering hacks or exploits of poorly constructed network rules and badly configured proxies. SCA scanning was something you needed to do, because that 2nd or 3rd line of defense is still important, but there was no need to declare a national emergency over every published CVE when it was only a few at a time that required the highest degree of attention.

And if you really want to get into the weeds of software security posture, it’s the use of older, unmaintained software that’s a lot more dangerous that a published CVE. A published CVE for an active open source project that scores high on CVSS 3/4 will get fixed pretty quickly, whereas you’ll be lucky if an expoit of unmaintained software will even be published in a CVE, much less fixed. The fact is that enterprises would be better off spending that money hiring maintainers of the software most critical to them. Those millions of dollars padding the salaries of SCA vendor executives should really go to the people who maintain the software, helping them provide better security so that the ecosystem at learge benefits. But see, SCA vendors were never really interested in solving the problem; they just wanted you to be scared enough to pay them extortion fees. In return, they overstated the security threat and overstated their importance in improving your security posture.

For inexplicable reasons, this industry category has been around for over 20 years now, and it is finally dying. Agentic engineering systems are rendering it null and void. This is ironic, because autonomous agents are able to find and exploit vulnerable software faster than ever, so you might think that SCA tools are needed more than ever. And yet, it’s the agentic tools that can now find and fix vulnerabilities just as quickly. In fact, agentic systems uncover and fix vulnerabilities so quickly that there’s little time to publish vulnerability data in a dumb metadata library. This is going to accelerate so quickly that the need for SCA scanning, such that it ever existed, will approach zero. Why would I need an SCA scanner when the software in question has already been updated, with a fixed version published for my consumption? Why would I need a predictive analysis tool when I can systematically retrieve the fixed versions of software as quickly as you can publish the software metadata? That’s just it: I won’t need a predictive analysis tool. Just give me the bits.

Death to SCA vendors. May they waste away slowly and painfully.
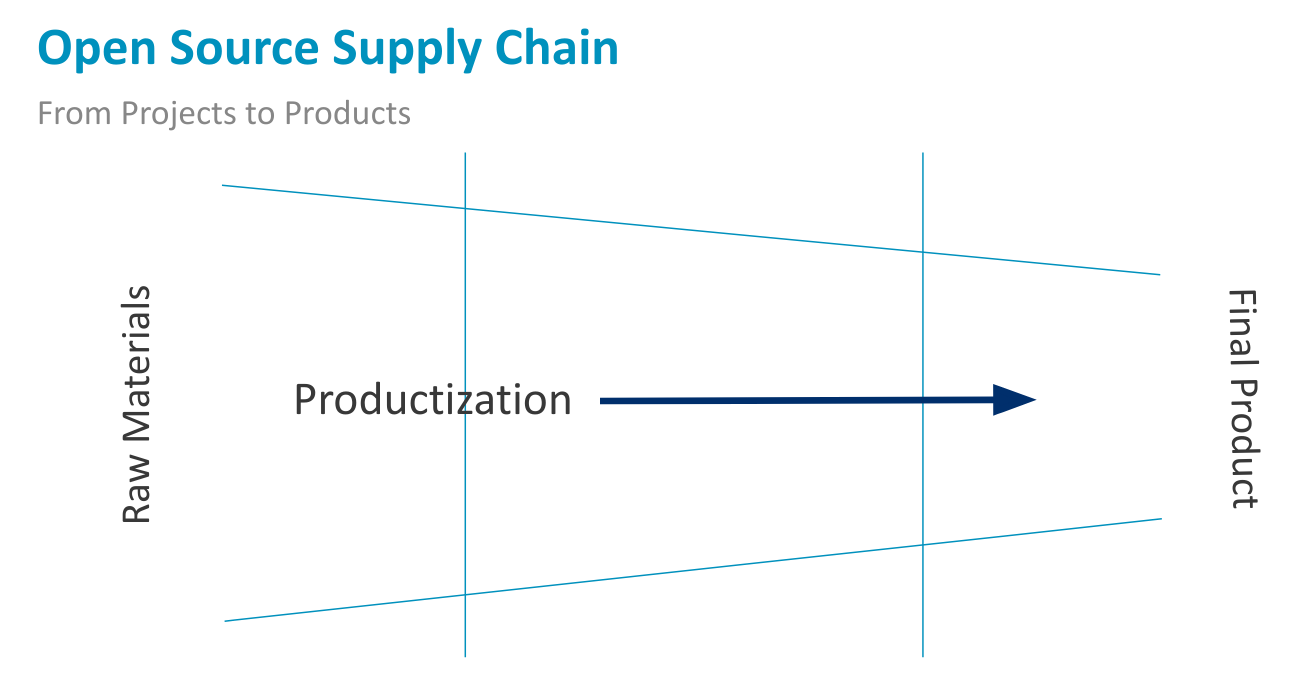
Diamgram of a supply chain funnel, showing raw materials on the left and finished product on the right. The title is "open source supply chain" with the subtitle "from projects to products"
commentary, supply chain

AI Native and the Open Source Supply Chain

I recently wrote 2 essays on the subject of AI Native Automation over on the AINT blog. The gist of them is simple:

It’s that latter point that I want to dive a bit deeper into here, but first a disclaimer:

We have no idea what the ultimate impact of "AI" is to the world, but there are some profoundly negative ramifications that we can see today: misinformation, bigotry and bias at scale, deep fakes, rampant surveillance, obliteration of privacy, increasing carbon pollution, destruction of water reservoirs, etc. etc. It would be irresponsible not to mention this in any article about what we call today "AI". Please familiarize yourself with DAIR and it's founder, Dr. Timnit Gebru.

When I wrote that open source ecosystems and InnerSource rules were about to become more important than ever, I meant that as a warning, not a celebration. If we want a positive outcome, we’ll have to make sure that our various code-writing agents and models subscribe to various agreed-upon rules of engagement. The good news is we now have over 25 years of practice for open source projects at scale that gives us the basis to police whatever is about come next. The bad news is that open source maintainers are already overwhelmed as it is, and they will need some serious help to address what is going to be an onslaught of “slop”. This means that 3rd party mediators will need to step up their game to help maintainers, which is a blessing and a curse. I’m glad that we have large organizations in the world to help with the non-coding aspects of legal protections, licensing, and project management. But I’m also wary of large multi-national tech companies wielding even more power over something as critical to the functioning of society as global software infrastructure.

We already see stressors from the proliferation of code bots today: too many incoming contributions that are – to be frank – of dubious quality; new malware vectors such as “slopsquatting“; malicious data injections that turn bots into zombie bad actors; malicious bots that probe code repos for opportunities to slip in backdoors; etc – it’s an endless list, and we don’t yet even know the extent to which state-sponsored actors are going to use these new technologies to engage in malicious activity. It is a scary emerging world. On one hand, I look forward to seeing what AI Native automation can accomplish. But on the other, we don’t quite understand the game we’re now playing.

Here are all the ways that we are ill prepared for the brave new world of AI Native:

  • Code repositories can be created, hosted, and forked by bots with no means to determine provenance
  • Artifact repositories can have new projects created by bots with software available for download before anyone knows no humans are in the loop
  • Even legitimate projects that use models are vulnerable to malicious data injections, with no reliable way to prove data origins
  • CVEs can now be created by bots, inundating projects with a multitude of false positives that can only be determined by time-consuming manual checks
  • Or, perhaps the CVE reports are legitimate, and now bots scanning for new ones can immediately find a way to exploit one (or many) of them and inject malware into an unsuspecting project

The list goes on… I fear we’ve only scratched the surface of what lies ahead. The only way we can combat this is through the community engagement powers that we’ve built over the past 25-30 years. Some rules and behaviors will need to change, but communities have a remarkable ability to adapt, and that’s what is required. I can think of a few things that will limit the damage:

  • Public key architecture and key signing: public key signing has been around for a long time, but we still don’t have enough developers who are serious about it. We need to get very serious very quickly about the provenance of every actor in every engagement. Contributed patches can only come from someone with a verified key. Projects on package repositories can only be trusted if posted by a verified user via their public keys. Major repositories have started to do some of this, but they need to get much more aggressive about enforcing it. /me sideeyes GitHub and PyPi
  • Signed artifacts: similar to the above – every software artifact and package must have a verified signature to prove its provenance, else you should never ever use it. If implemented correctly, a verified package on pypi.org will have 2 ways to verify its authenticity: the key of the person posting it, and the signature of the artifact itself.
  • Recognize national borders: I know many folks in various open source communities don’t want to hear this, but the fact is that code that emanates from rogue states cannot be trusted. I don’t care if your best friend in Russia has been the most prolific member of your software project. You have no way of knowing if they have been compromised or blackmailed. Sorry, they cannot have write access. We can no longer ignore international politics when we “join us now and share the software”. You will not be free, hackers. I have to applaud the actions of The Linux Foundation and their legal chief, Michael Dolan. I believe this was true even before the age of AI slop, but the emergence of AI Native technologies makes it that much more critical.
  • Trust no one, Mulder: And finally, if you have a habit of pulling artifacts directly from the internet in real time for your super automated devops foo, stop that. Now. Like.. you should have already eliminated that practice, but now you really need to stop. If you don’t have a global policy for pushing all downloads through a centralized proxy repository – with the assumption that you’re checking every layer of your downloads – you are asking for trouble from the bot madness.
  • Community powered: It’s not all paranoid, bad stuff. Now is a great opportunity for tech companies, individual developers, enterprises, and software foundations to work out a community protocol that will limit the damage. All of these actors can sign on to a declaration of rules they will follow to limit the damage, quarantine known bad actors, and exchange vital information for the purpose of improving security for everyone. This is an opportunity for The Linux Foundation, Eclipse, and the Open Source Initiative to unite our communities and show some leadership.
  • Bots detecting bots: I was very hesitant to list this one, because I can feel the reactions from some people, but I do believe that we will need bots, agents, and models to help us with threat detection and mitigation.

I have always believed in the power of communities to take positive actions for the greater good, and now is the perfect time to put that belief to the test. If we’re successful, we can actually enjoy revamped ecosystems that will be improved upon by our AI Native automation platforms. If successful, we will have safer ecosystems that can more easily detect malicious actors. We will also have successful communities that can add new tech capabilities faster than ever. In short, if we adapt appropriately, we can accelerate the innovations that open source communities have already excelled at. In a previous essay, I mentioned how the emergence of cloud computing was both a result of and an accelerant of open source software. The same is true of AI Native automation. It will inject more energy into open source ecosystems and take them places we didn’t know were possible. But what we must never forget is that not all these possibilities are good.

commentary, supply chain

The Revenge of the Linux Distribution

Some things appear in hindsight as blindingly obvious. And to some of us, perhaps they seemed obvious to the world even at the time. The observations of Copernicus and Galileo come to mind. To use a lesser example, let’s think back to the late 2000s and early 2010s when this new-fangled methodology called “devops” started to take shape. This was at a moment in time when “just-in-time” (JIT) was all the rage, and just-in-time continuous integration (CI) was following the same path as just-in-time inventory and manufacturing. And just like JIT inventory management had some weaknesses that were exposed later (supply chain shocks), so too were the weak points of JIT CI similarly exposed in recent security incidents. But it wasn’t always thus – let’s roll back the clock even further, shall we?

Party like it’s 1999

Back when Linux was first making headway towards “crossing the chasm” in the late 90s, Linux distributions were state of the art. After all, how else could anyone keep track of the all the system tools, core libraries, and language runtime dependencies without a curated set of software packaged up as part of a Linux distribution? Making all this software work together from scratch was quite difficult, so thank goodness for the fine folks at Red Hat, SuSE, Caldera, Debian, and Slackware for creating ready-made platforms that developers could rely on for consistency and reliability. They featured core packages by default that would enable anyone, so long as they had hardware and bandwidth, to run their own application development shop and then deliver those custom apps on the very same operating systems, in one consistent dev-run-test-deploy workflow. They were almost too good – so good, in fact, that developers and sysadmins (ahem, sorry… “devops engineers”) started to take them for granted. The heyday of the linux distribution was probably 2006, when Ubuntu Linux, which was based on Debian, became a global phenomenon, reaching millions of users. But then a funny thing happened… with advances in software automation, the venerable Linux distribution started to feel aged, an artifact from a bygone time when packaging, development, and deployment were all manual processes, handled by hand-crafted scripts created with love by systems curmudgeons who rarely saw the light of day.

The Age of DevOps

With advances made in systems automation, the question was asked, reaching a crescendo in the early to mid-2010’s, “why do we need Linux distributions, if I can pull any language runtime dependency I need at a moment’s notice from a set of freely available repositories of artifacts pre-built for my operating system and chip architecture? Honestly, it was a compelling question, although it did lead to iconic graphics like this one from XKCD:

For a while it was so easy. Sure, give me a stripped down platform to start with, but then get the operating system out of the way, and let me design the application development and deployment layers. After all, any competent developer can assemble the list of dependencies they will need in their application. Why do I need Red Hat to curate it for me? Especially when their versions are so out of date? The rise of Docker and the race to strip down containers was a perfect example of this ethos.

A few incidents demonstrated the early limitations of this methodology, but for the most part the trend continued apace, and has remained to this day. But now it feels like something has changed. It feels like curation is suddenly back in vogue. Because of the risks from typo-squatting, social engineering hacks, and other means of exploiting gaps in supply chain security, I think we’ve reached somewhat of a sea change. In a world where the “zero trust” buzzword has taken firm hold, it’s no longer en vogue to simply trust that the dependencies you download from a public repository are safe to use. To compensate, we’ve resorted to a number of code scanners, meta data aggregators, and risk scoring algorithms to determine whether a particular piece of software is relatively “safe”. I wonder if we’re missing the obvious here.

Are We Reinventing the Wheel?

Linux distributions never went away, of course. They’ve been around the whole time, although assigned to the uncool corner of the club, but they’re still here. I’m wondering if now is a moment for their return as the primary platform application development. One of the perennial struggles of keeping a distribution up to date was the sheer number of libraries one had to curate and oversee, which is in the tens of thousands. Here’s where the story of automation can come back and play a role in the rebirth of the distribution. It turns out that the very same automation tools that led some IT shops to get too far ahead over their skis and place their organizations at risk also allow Linux distributions to operate with more agility. Whereas in the past distributions struggled to keep up the pace, now automated workflows allow curation to operate quickly enough for most enterprise developers. Theoretically, this level of automated curation could be performed by enterprise IT, and indeed it is at some places. But for teams who don’t have expertise in the area of open source maintainership or open source packaging, the risk is uncertain.

Is It Time for a Comeback?

I don’t know for a fact that Linux distributions are poised to return to the center of application development, but I do know that much of what we’re doing to isolate and mitigate risk – security scanning, dependency curation, policy enforcement, and scorecards – feels an awful lot like what you get “out of the box” with a distribution. Enterprise IT has moved to a different delivery model than what existed previously, and moving away from that is not trivial. But if I were looking to start an organization or team from scratch, and I wanted to reduce the risk of supply chain attacks, I would probably elect to outsource risk mitigation to a curated distribution as much as possible.
podcast, supply chain, syndicate

Podcast: Shane Coughlan of Openchain

Shane Coughlan is the founder and manager of the Openchain Project, which “builds trust in open source by making open source license compliance simpler and more consistent.” As any software asset management person can tell you, they get cross-eyed when it comes to open source license compliance. My opinion has always been that this was due to lack of information outside of the immediate sphere of open source developers. The Openchain Project aims to remedy that, and in this podcast we talked about the challenges of doing that. It’s a great listen!

news

Open Source Supply Chain “Full of Bugs”

From EnterpriseTech: I came across a link today to a news commentary which asserts that open source software is “a supply chain rife with security vulnerabilities and clogged with outdated versions of widely used software components.” I’m often reluctant to give these types of stories too much air time, because they’re often rife with FUD, but there’s a lot of truth here, and it’s something that we need to face up to, especially if we want companies to continue to innovate on open source platforms and build open source products.

If you read Nadia Eghbal‘s “Roads and Bridges” white paper for the Ford Foundation, you’ll see that crusty, old open source software has been a concern for some time. She proposes that we view software the same as any other core infrastructure, such as roads and bridges. There’s also a collaborate project from the Linux Foundation, the Core Infrastructure Initiative, to attempt to deal with these issues.

This is not an easy problem to solve, and it hits at the hears of what we want to do at the Open Source Entrepreneur Network, because we want companies to build process around their consumption and contribution of this great open source software and make contingency plans for when it all goes haywire. We want companies to be able to reduce their risk exposure while still benefiting from the innovation happening right now on open source platforms.

supply chain

Managing Your Supply Chain

Depending on open source software introduces some challenges for those looking to create products or services derived from upstream open source components. There’s a lot to consider regarding risk management, engineering efficiency, and how to influence the nebulous upstream open source world – and why you should. Original content was published at opensource.com: